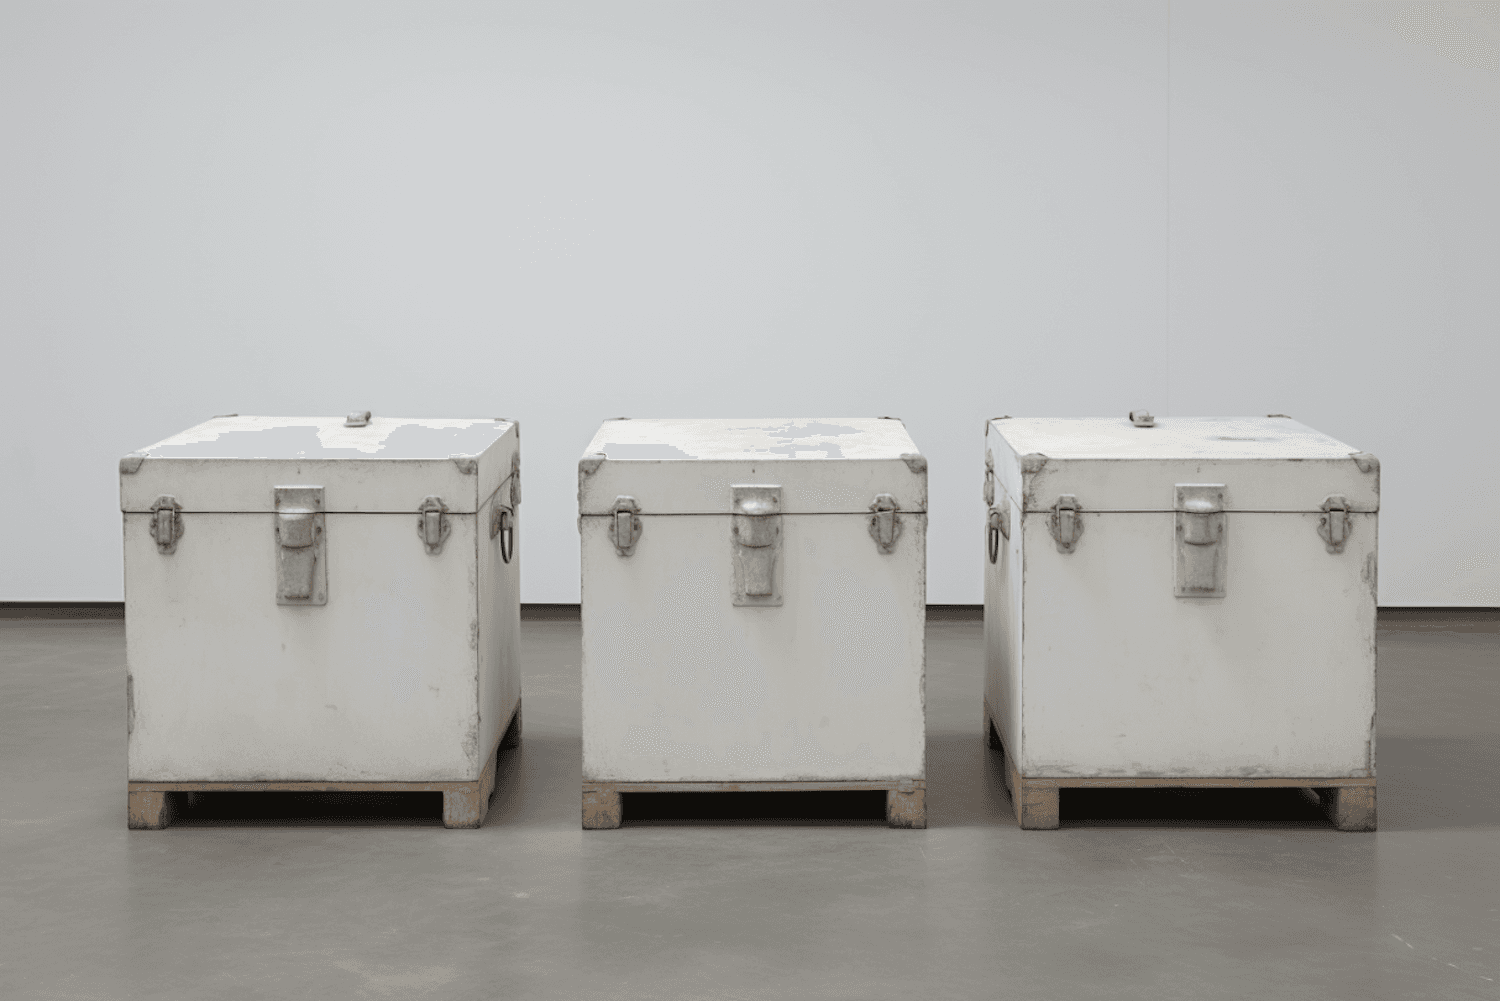
AMR / Manipulation
Autonomous mobile robots
First-person egocentric motion, object gripping, and industrial floor navigation.
- Egocentric motion
- Object gripping
- Floor navigation
Enterprise multimodal and
physical AI data pipelines
Data infrastructure for AI
Modalities and outputs
(01)The input layer
We replace synthetic gaps and scraped noise with real-world data your model can learn from. Every asset is rights-cleared, consent-verified, anonymized, and annotated before it reaches your bucket.
IP-cleared
100%
IP-cleared sourcing and commercial use.
Contributors
Vetted
Verified contributors with annotation background.
Privacy
PII-safe
Frame-by-frame face and plate blurring.
Delivery
S3 / GCP
Direct pipeline and bucket export.
(02)Services
Source, access, and structure high-value inputs without stitching together disconnected vendors.
Tell us your spec. We deploy vetted contributors to capture edge-case egocentric and spatial video.
Instant access to IP-cleared, consensual multi-speaker and physical interaction feeds.
Frame-level temporal tagging, bounding boxes, and active speaker diarization exported directly to S3.
(03)Pipeline architecture
One accountable layer for sourcing, quality, privacy, annotation, and delivery.
Real video from vetted contributors, collected across egocentric, conversational, and spatial environments.
Quality checks, PII blurring, active speaker diarization, temporal tags, and frame-level annotation before delivery.
Structured Parquet and JSON manifests sync directly to your model stack, S3, GCP, or downstream API.
(04)Built for the hard parts
Targeted collection and annotation for high-value edge cases across physical and multimodal AI. Hover a card to see the raw frame behind the dots.
Request a sample batchAMR / Manipulation
First-person egocentric motion, object gripping, and industrial floor navigation.
Audiovisual speech
Direct-to-camera speech, facial expression streams, diarization, and localized dialogue.
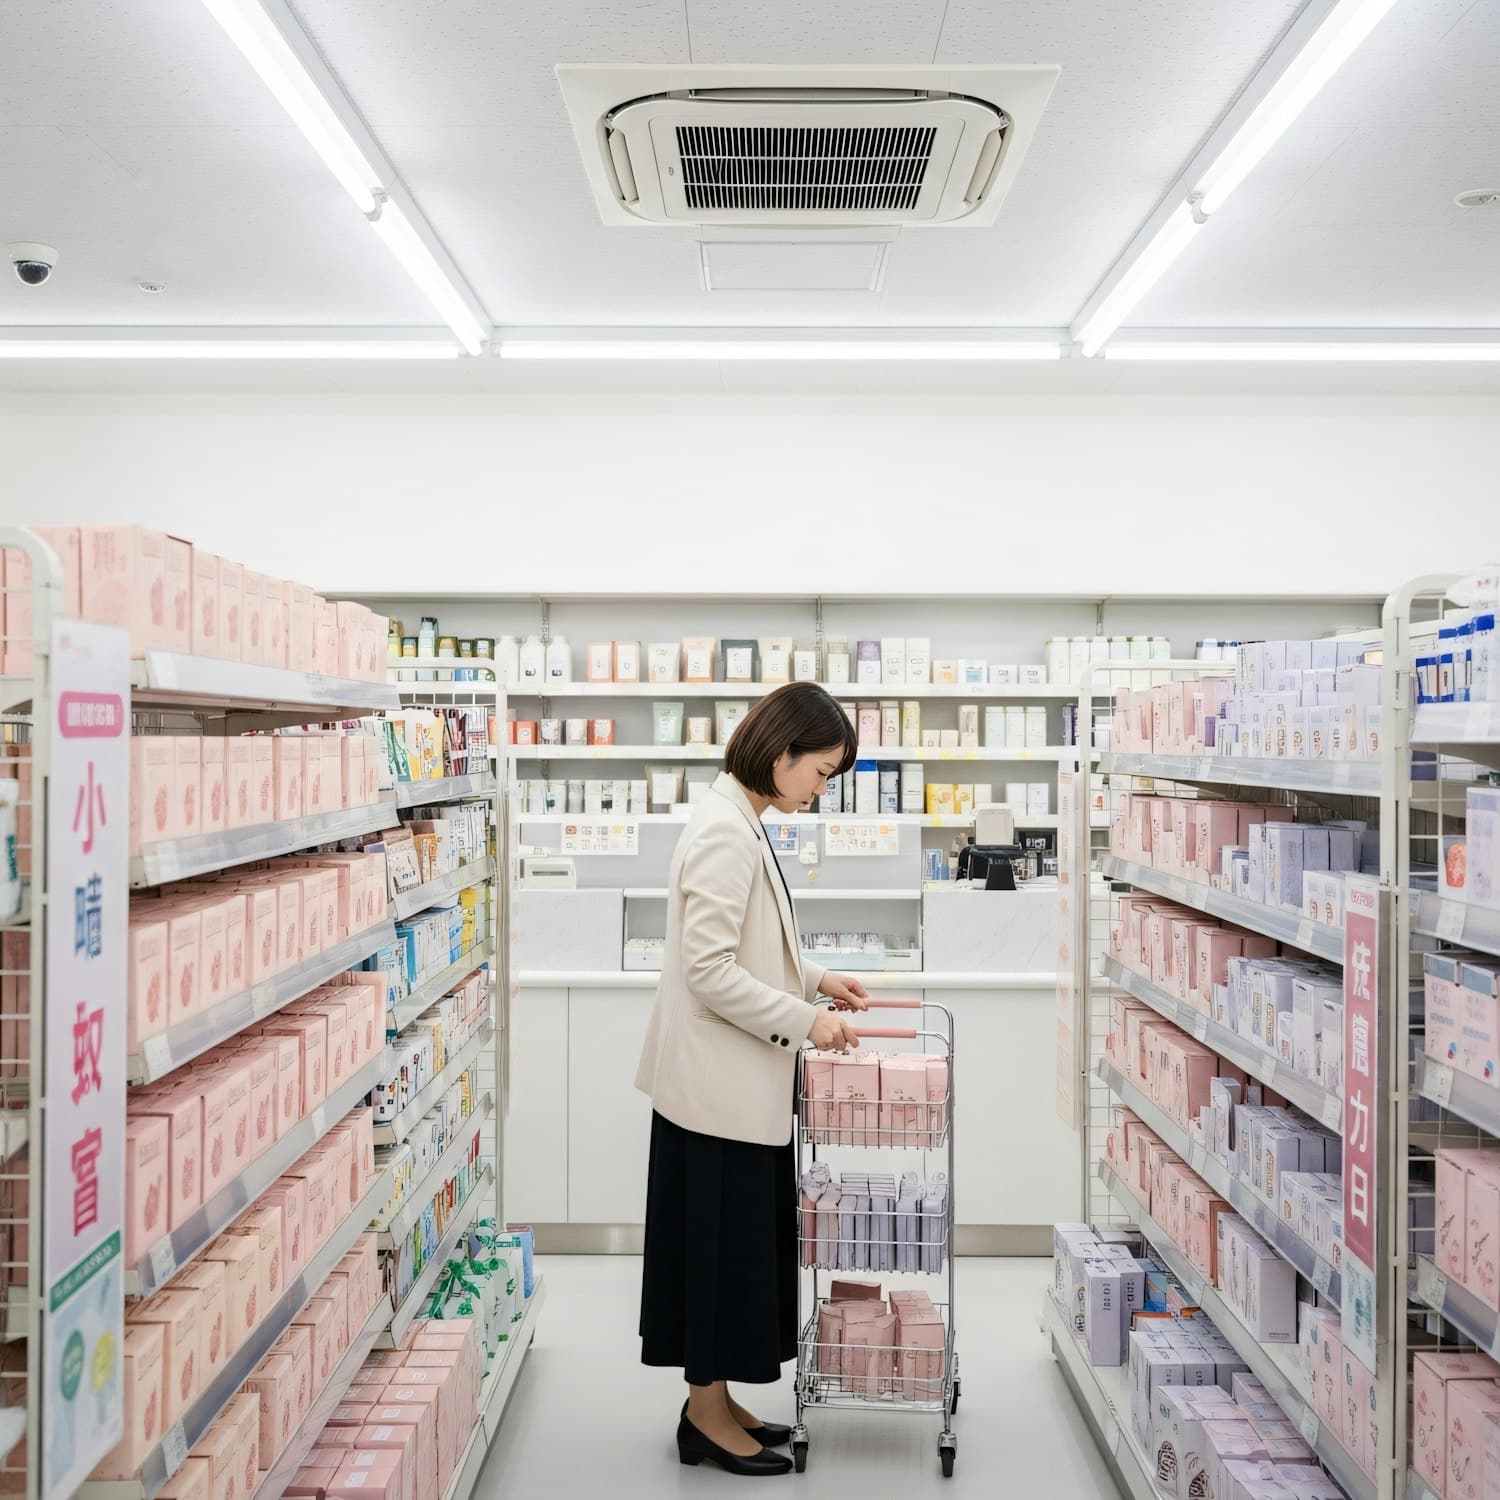
Retail CV
Shelf scans, price tag recognition, and multi-angle indoor spatial telemetry.
3D / Depth
Point clouds and depth map pairs for spatial understanding and AR models.
Robustness
Variable lighting, outdoor transitions, and unscripted obstacle feeds.
VLA / Foundation
Synchronized video, audio, and transcript datasets for pre-training and fine-tuning.
(05)Show, do not tell
Our delivery layer turns raw media into structured, queryable training inputs with synchronized metadata and verification states.
{"asset_id": "spatial_004821","modality": "egocentric_video","duration_s": 42.8,"pii_status": "verified_clear","imu_stability": 0.984,"annotation": "action_temporal_v2"}Sample deliveries. Hover the frame to see the raw footage.
(06)Ready for a better input layer?
Tell us about your project and data requirements. Our team will reach out to schedule a consultation and build a sourcing plan tailored to your model.
